Playbook: the forecast said all is well — was it ever right?
The situation
The engine has been warning about stockouts and late orders for months. Some warnings were acted on, some ignored. Nobody can say how often they were right — so nobody knows how much to trust the next one.
Step 1 — Score the predictions
Open Command → Accuracy & calibration.
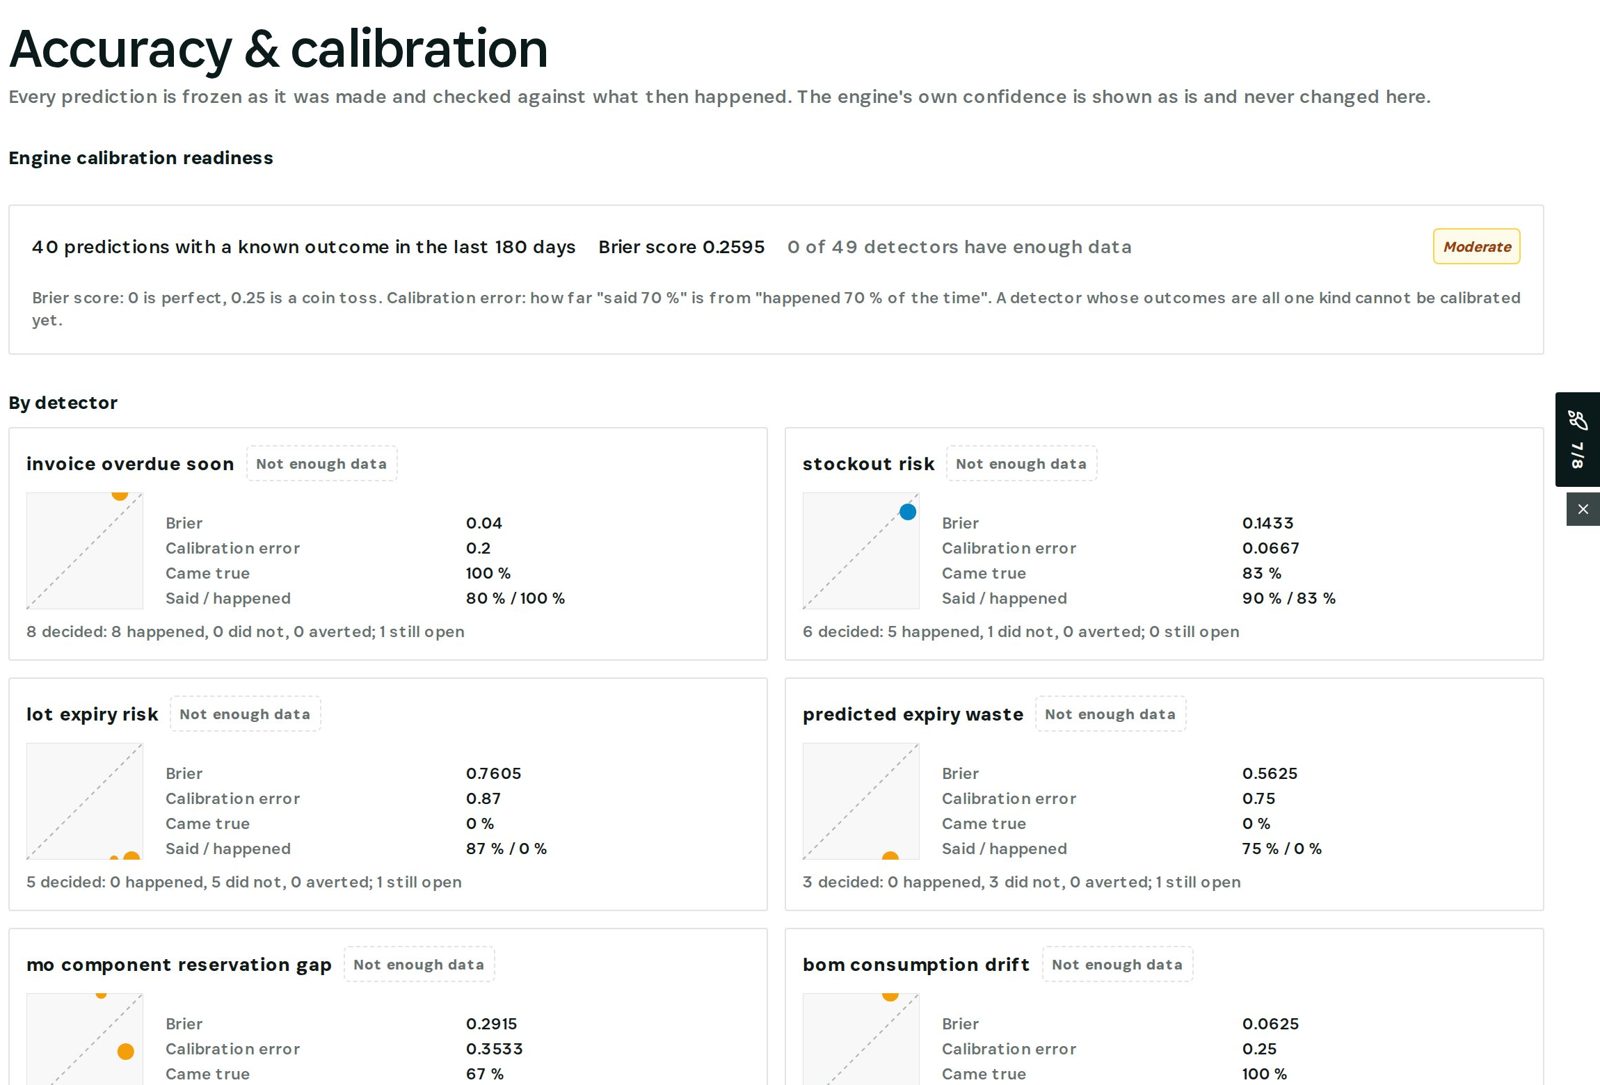
In the demo, forty predictions have known outcomes over the last six months, with a Brier score of about 0.26 — close to a coin toss — and no detector yet with enough data to be called calibrated. That is an honest answer: trust is earned per detector, as outcomes accumulate. The engine's own confidence is shown as is and never adjusted here.
Step 2 — Forecasts with a range
Open Command → Forecasts.
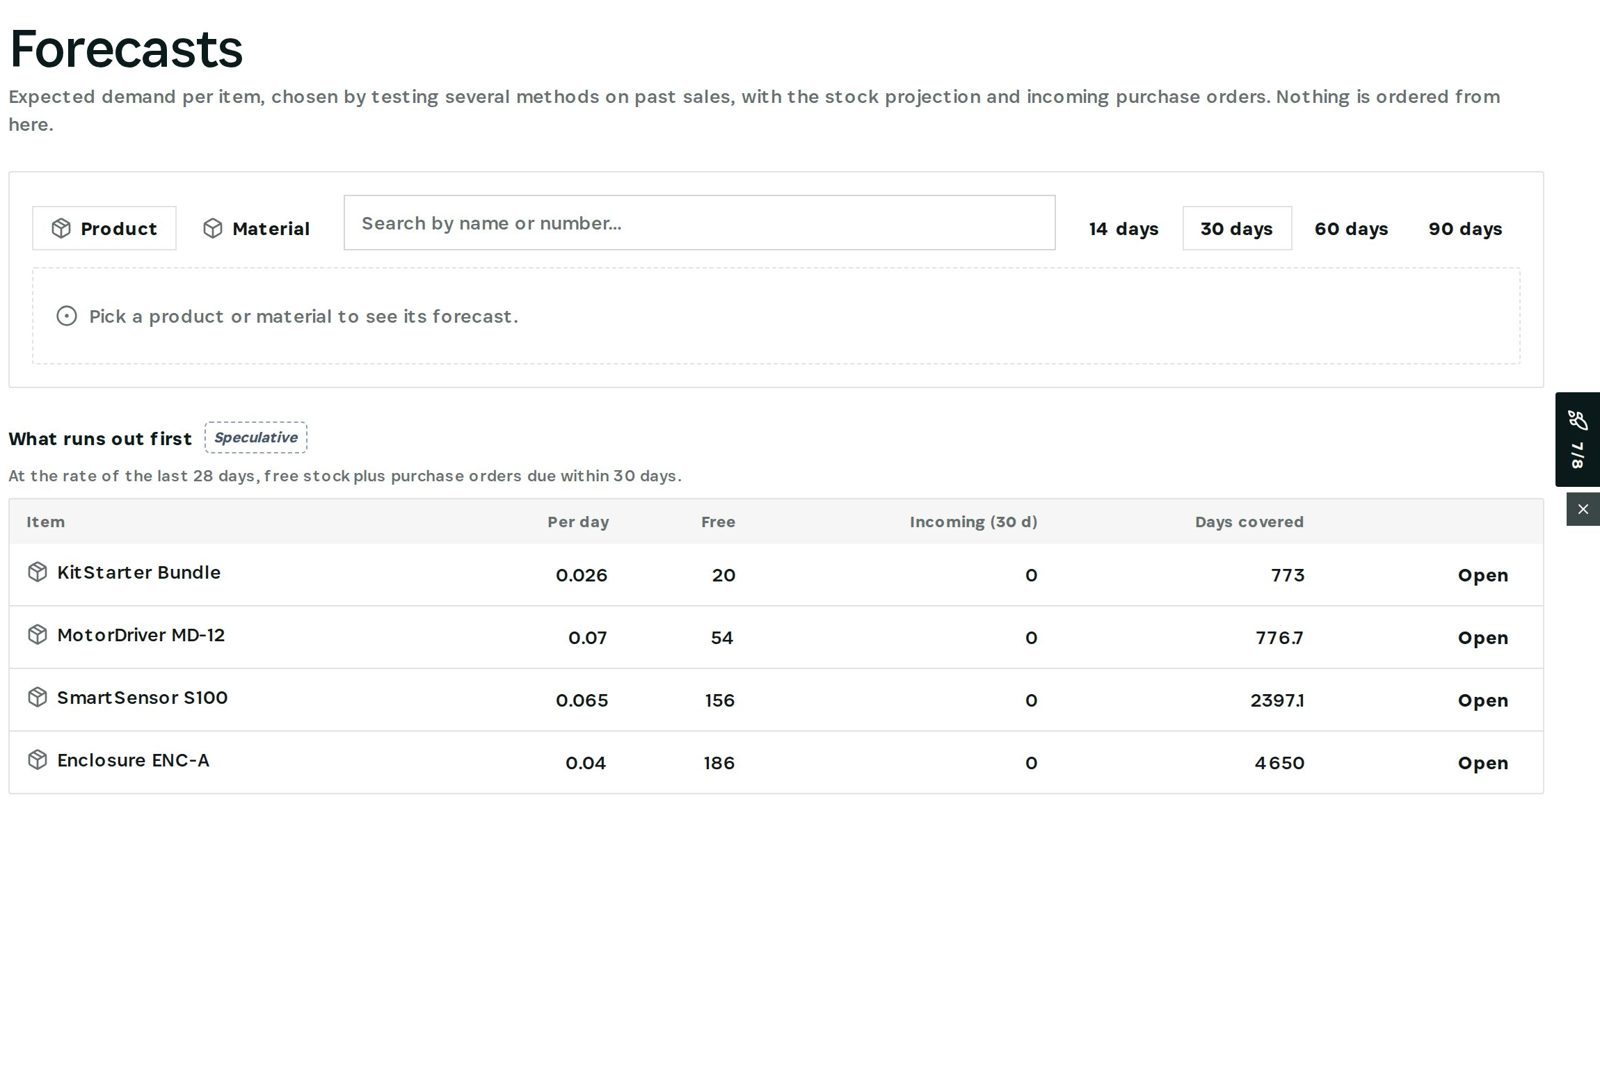
What runs out first ranks items by days of cover from recent sales, free stock and purchase orders due. Pick an item to see its expected demand — chosen by testing several methods on its own history — with an eighty percent range, and Freeze the forecast to check it later.
Why it matters
A model is only useful if you know how wrong it can be. Freezing predictions makes the score honest: nothing can be improved after the fact.
What you have at the end
- Every prediction scored against what happened.
- Readiness per detector, not blind trust.
- Forecasts with a range, frozen for later checks.
Screenshots come from the Otiox demo workspace. Choose Switch to demo in the sidebar to follow along; changes there never touch live data. Command reads your records and never changes them.